AI Setup Evolution

I’ve been writing a lot about AI and tech projects lately, which makes sense since that’s the stuff that ends up on this blog. It isn’t all that’s going on in my life, just to be clear. But my AI setup has quietly evolved in August and September in a way that’s letting me undo a bunch of stuff I only built because of the cloud AI’s limitations, so here we go again.

First, the accounts. I’ve been using Claude a lot more than any other AI system lately, but I’m still mixed between Claude and ChatGPT for coding work. Instead of paying for Claude Max or the equivalent top tier ChatGPT plan, which run about five times the price of the regular subscription, I pay for two mid tier plans instead, the Claude Pro and the ChatGPT Plus. Partly that’s so when I run out of tokens on one, I can switch to the other. But that’s a small reason. The bigger ones are that if one gives me a bad answer, I want to try the other, and sometimes I want a second opinion and will ask both the same question. I also don’t think I’d actually use five times the usage, so paying for the bigger plan on either one would just mean I’m not getting my money’s worth. There are times I max out both in the same stretch, so maybe I am doubling up after all. Who knows.

Interesting side note, I’ve been leaning on Codex more for coding lately, with a bit of chat here and there. I like their interactive audio, though I don’t use it as much as I probably hold onto the idea of using it. I’m building sites and things with Codex now, not because I think it’s better, I started because a friend recommended it after I hit a specific wall with Claude. I still use Claude for coding too, but I keep them separate on purpose. Coding work tends to run a project’s token budget down fast, and I don’t want that eating into the day to day chatting I do in Claude. The coding side is pretty interchangeable between the two since everything gets saved locally to wherever I’m working anyway.

Now, the actual problem I’ve been solving. With ChatGPT, and then Claude once I moved to it, the challenge was always context. Take my car tracking prompts as an example. It’s one of many, holiday planning is another, so is tracking the general inventory of stuff I own, but let’s stick with the car since we’re actually replacing it with another used one right now. I’d feed it a lot of detail about the car, our usage, our spending, all of that. Then every new chat, I wanted it to already know the context, how to respond to me for that narrow kind of conversation. So I had some generic prompts, plus a very specific auto inventory prompt, and I’d load all of that into a fresh chat every time.

Then there’s the data itself. Registration, MOT dates, how much we paid for the car, fuel spend over the last couple of months. All stuff AI is genuinely good at trending and drawing insight from, and useful for research too. But I needed to save it somewhere. My old process was to have the prompt itself describe how to save the data, which in most cases meant getting the AI to structure everything into a JSON file I could download and keep a version of.

The problem is I don’t want to keep an indefinite chat going, especially with Claude, though ChatGPT has some of the same issue. As a chat gets long, the AI starts forgetting the earlier stuff and compacts it, and it even warns you this is happening. I wanted everything solid enough that if I deleted that chat and started fresh, the new one would already have everything the old one had.

So the prompts were only half the system. The other half was the JSON, or a CSV for a pure inventory file, sitting there holding the actual data. I built one of these little systems for the car, one for holiday planning, one for holiday budgeting, a stack of them, each with its own context switch. It worked, but it meant a real proliferation of chats. Start a chat, load the data, double check which version of the file I was working from, and when I was done for the day, have the AI spit out a fresh JSON with a version number in the filename and save it to disk. I ended up with thirty or forty versions of some of these files sitting around. Not done with the topic forever, just done with it for that session, so I’d save and move on, and next time load the latest one and keep going.

That whole dance existed because neither Claude nor ChatGPT could write to a file in its own project folder, only read from one. I could load something into a project, but I couldn’t have it write back out to that same spot. That was the actual limitation driving all of it.

Then, much more recently, within the last month or so, Claude’s Cowork got a lot easier to use and a lot more functional. It’s mid September as I’m writing this, and just yesterday I read that they’d simplified the interactions with it even further, which is great timing for me. With Cowork, I’ve gone back through each of my little systems and rewritten the prompts. Now I can just tell a new chat to look at a directory on my computer, read the markdown file with the instructions, read the JSON, and write straight back to that same JSON. No more versioning gymnastics on my end, because I don’t need to care about it anymore. Time Machine on my Mac is already snapshotting everything hourly and backing it up elsewhere, so the versioning is handled at the file system level, which is where it belonged all along.

I still keep these as separate projects in Claude, because I want specific context tied to specific folders on my computer. My car information lives under an auto folder inside a broader life inventory folder, my computers have their own folder, my domain names have theirs, each with its own markdown for how I want it handled. In the past I’d have to manually load the data file and the instructions file into Claude every single time I started up. Now the project just has a tiny instruction pointing to a markdown router, a file in the root directory that lists out all the different contexts I’ve got and where to find the detailed files for each one. It knows to go look in those folders, and inside something like auto, it’ll find an instructions markdown, the data file, and whatever else belongs there. I can start one omni chat for anything life inventory related, or a specific car chat, and either way it’s not my job to keep the local files in sync anymore, because that’s just handled.

For a while I could already do a version of this on my own computer in a coding session, but not from the cloud, not from my phone on the couch, or my iPad while we’re figuring out where to go for dinner or nailing down holiday plans. Now with Cowork, I can start a session that runs as long as it needs to. I don’t care if it compacts and forgets things partway through, because all the data that matters is already saved to a file, and it’s got a remote session into my actual computer at home.

In another post I mentioned why I might end up getting a Mac Mini instead of relying on my MacBook Air, and this is exactly why. If I take the laptop with me, none of these sessions work, since there’s no computer at home to remote into. I’m fine with a dedicated home machine for this, because lately the only reason I’ve been taking a laptop anywhere has been to do AI stuff with it in the first place. It’s a bit circular. If I can run everything through a remote Cowork session back to a computer at home, I don’t need to bring a computer anywhere at all.

I’ve been going on holiday without a computer for a while now, aside from that one AI use case, to the point where I’ve packed the laptop a couple of times telling myself I might need it, and then never actually taken it out of the bag. My 11 inch iPad Pro has become my go to screen for everything, and this new Cowork setup makes that even more true than it already was.

So that’s where things have migrated to for now, and we’ll see how it keeps evolving. Ideally I’d love to get to a point where I don’t need a home computer in the loop at all and can just use remote storage instead. But I don’t use a mainstream service like Dropbox, OneDrive, or Google Drive, which is probably where that kind of direct read and write access would actually get supported first. Last I checked, Google at least would let you read from those places but not write back to them. When that changes, it’ll be worth revisiting, but for now I’m sticking with my own storage.

That’s the state of the AI setup as it stands. Check back in a couple of months to see how much of this I’ve already torn apart and rebuilt again.
AI For the Mundane Stuff…

I have been using AI for increasingly mundane things I always meant to do but never actually got around to. Most recently, a mystery Mac DMG file.

I had a Mac DMG file. About eight gigs. Password protected. I have no idea why I password protected it. I knew roughly what was in it, a big archive of installer packages going back years, but I could not get in because the password I thought it was was not working.

I have been saving installers since back when software did not just update itself over the internet and you actually needed to hold onto major versions. Over time the archive grew across different Mac architectures. PowerPC stuff, then x86 and Universal binaries, and now arm64. So there is a lot in there going back a long time.

I put Claude on the case. I gave it my best guesses at what the password might be, because I did not want it going through every possible combination until the end of time, and it set up a cracking tool locally on my MacBook Air and let it run with those hints. It got in.

So now I had all this data, plus a bunch of other old archives, and the problem was figuring out what was what. File dates only get you so far. Some of it was obvious, certain versions of Microsoft Office are a dead giveaway for the era and architecture. But a lot of it was not.

This matters because I have two PowerPC Macs I picked up vintage that I actually want to use, and I have been thinking about picking up an older Intel Mac for similar reasons. Half of it is just because it is cool to have. The other half is that occasionally I do want to run some old software. So getting the right installer on the right machine is not a trivial question.

A few prompts later, Claude had written a set of scripts that parsed through everything, sorted it by architecture, and organised it all into the right folders. A few back and forth sessions where it asked me questions and I confirmed things, and it had a pretty solid result.

Then I went a step further. I had it size and create read only DMG images for each architecture, correctly sized so the PowerPC stuff would fit on a DVD if I want to burn one, or on a USB key I can move to one of the older machines. Right file systems, right sizes, the lot. About 100 gigs of stuff in total so it took a while to churn through, but my actual involvement was maybe 20 to 30 minutes of back and forth.

I had wanted to do this for years. Total elapsed time was maybe three hours, almost all of it the computer doing the work.

Now it is all backed up, the images are ready, and whenever I get around to spinning up those old machines I can actually do it. Which might not be for a while. But at least now I can.

Collecting AI Models Like It’s a Hobby

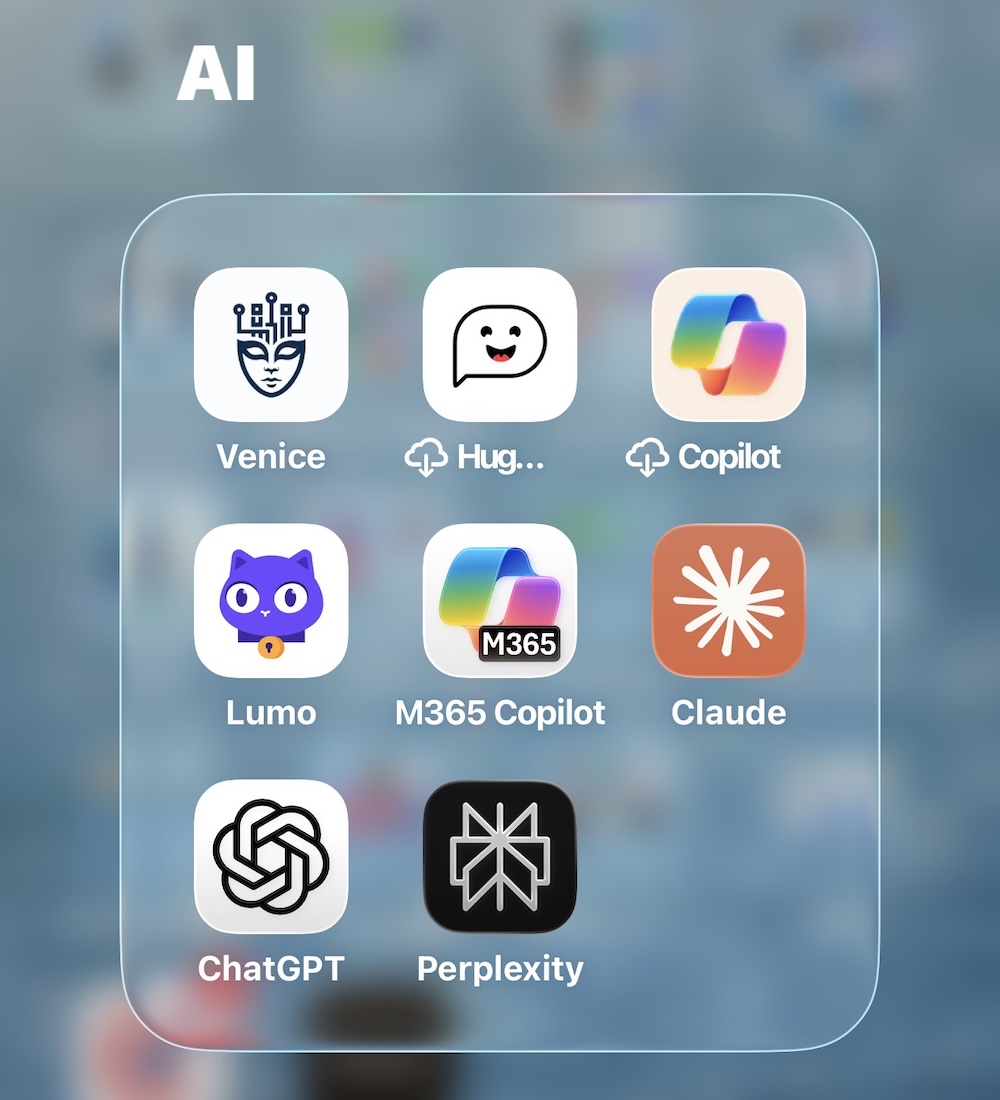
It’s almost like I collect AI models and providers. Each one has its own use case, and I probably could consolidate. But in some situations it’s not even worth the effort to do it.

As of writing this in early May 2026, and I mention the date because I usually have a backlog of a couple of months before things go live, my main tool is Claude. Well worth the money and then some.

But in addition to that I’m paying for Venice.AI as my privacy AI. Very cheap per year, limited use case, but for what it does it’s worth every penny.

Then there’s Lumo from Proton. I’m about one week into an experiment of not using it to see if I actually miss it. The honest answer is probably not, because I’m now running local models on my new MacBook Air with 32 gigs of RAM, which I got specifically to be able to do this. I’ve been running Mistral 3 3B locally and early results suggest it might actually be more private and more capable than Lumo for what I need it for. So that £120 a year might be on its way out.

I also have Perplexity Pro, which I don’t actually pay for directly. It comes bundled with another subscription I have. It’s slightly better than the others for web search type queries so I use it for that. Would I pay for it separately? Probably not. But I have it so I use it.

And then there’s ChatGPT. I touched on this in the last post but I’m currently trialling whether running Claude Code and ChatGPT’s Codex side by side is actually cheaper than paying for the next Claude tier up. The overages on Claude Code have been real, and the maths might just work out. Still figuring that one out.

So yes, I have more models and services than I probably need. Lumo is the obvious cut. Beyond that I’m genuinely not sure. The ecosystem as a whole is delivering value right now, even if it’s a bit sprawling.

What I do know is that two years in, I’m using these tools in ways I couldn’t have imagined when I first paid for Copilot on a 30 day trial just to see what would happen. And the people I talk to who haven’t really dug in yet, I get it, it can feel overwhelming. But the gap between what you can do with these tools and what most people are doing with them is pretty wide right now. And that gap is only going to get wider.

Levelling Up to Claude Code

So I mentioned at the end of my last post about AI that switching to Claude unlocked a new level of what I was doing with it.

It started small. Someone at work mentioned they’d been using Claude Code to build actual apps, and they’re not a developer either. Just someone with ideas and enough curiosity to see what happens. That stuck with me.

I had a specific problem I wanted to solve. I have some VoIP numbers through my internet provider, actual UK mobile numbers I can receive texts on. Useful for giving out to LinkedIn contacts or anyone I don’t want having my main number. The problem was sending replies meant logging into a clunky website every time. Nobody wants to do that.

So I asked Claude about it. One thing led to another and it said it could help me build a web app for that. When I asked if we could run it in Docker it said of course. I already run Docker on a few systems at home so that made sense. It built me a container, I ran it on my Synology, got it working for one number, cloned it for a second. Then I thought, wait, can we just have one container with a dropdown to switch between numbers? Of course we can. And it did it.

That was the moment I thought, if it can build me an app with this level of input and time, what else can it really do?

So I set up Claude Code properly, gave it access to my Raspberry Pi setup, and had it take the SMS app further. It interrogated my existing config, made some enhancements, deployed everything from the command line. Straightforward, but impressive.

From there I got more ambitious. My blog had been running on YunoHost, which is a self-service VPS platform. Decent enough, but it’s always on an older version of Debian because the open source volunteers take what feels like a long time to update it, and if an app isn’t in their package store you’re out of luck. I’d always wanted to run my own properly configured stack but never wanted to deal with the time to care and feed it.

I had a spare VPS sitting around doing nothing. So I asked Claude, can we design and build my entire website on this thing. WordPress in Docker, proper backups, the works. It said yes.

First I designed the whole thing with Claude, got a proper design document together, then imported that into Claude Code and let it build. About $25 to $40 in API costs later I had a website. And not just a website. Automated daily backups following a daily, weekly, monthly cadence with pruning built in, all replicating to a second location with an immutable copy at the end. Backup infrastructure honestly better than some hosting providers I’ve heard about. I then migrated my site over to it, wiped the old setup, and migrated it back again just to prove I could restore it. All worked.

Then I got bold. I had the spare VPS now freed up, so I used it to build a set of personal tools I’d always wanted but never had the time to set up properly. An open source SSO system with passkey authentication for me and my wife. A Searx search instance sitting behind the SSO. Network monitoring. I didn’t even know I could set up my own SSO until Claude walked me through it. Some API costs and an afternoon later it was running.

Around the same time I set up a proper monitoring stack. My external VPS now watches my home internet connection and my main Raspberry Pi, and sends push notifications to my phone if anything goes down. Not email, because I’m not going to look at an email. An actual push notification. I also have a speed test running every hour on a gigabit ethernet connection straight into the router, and my internet provider, who I’ve never had a bad word to say about, is consistently delivering around 305 megabit on a 350 megabit plan. Seeing that graphed over time is genuinely satisfying.

All of that cost me some API charges, probably a couple of dollars worth, and £4 for a push notification app I now own outright. Not a subscription. Just mine.

Then I built a router.

I’d looked at this before. A router is basically just a computer with extra network cards, and I’d used open source router software in the past. But I’d always bought the manufacturer’s hardware because I didn’t want to deal with building and maintaining my own. This time I asked Claude to help me design and deploy it, and then help me maintain it going forward.

Of course It said yes. It can be a yes man/lady/person a lot.

I researched the hardware with Claude’s help and landed on a Protectli VP2430, a fanless little box with four 2.5 gigabit network ports and an Intel N150 processor. 16 gigs of RAM and a 256 gig SSD. Overkill for a router, which means it’ll last a long time. Then I designed the whole OpnSense configuration with Claude before touching any hardware.

Deployment was more painful than I expected. The biggest issue was needing the new router connected to my laptop while also needing live internet on the same laptop to use Claude to programme it. The address space decisions I’d made complicated things further. I spent six hours one evening and an entire Saturday on it before rolling back. Then I realised what was in the end the hurdle that had stopped me, made one design adjustment, tried again the following week, and had it running in about two hours. It’s been stable since.

I’m not a software developer. But I’ve spent years building and supporting data centres, call centres, and large scale applications, so I understand enough to know when something looks wrong and push back on it. I understand some scripting and basic fundamentals. What I can do is explain what I want clearly, spot when the output doesn’t smell right, and interrogate it until it does. That combination, it turns out, is enough to build some pretty serious stuff.

The things I’ve been able to do aren’t things I couldn’t have done before in theory. But the time to care and feed a self-hosted setup was always more than I was willing to put in. Now I have AI that helps me design it right, build it right, and fix it when something goes wrong. The barrier that used to stop me isn’t really there anymore.

So now I’m looking at what’s next. I have mockups for a couple of actual apps I want to build. Things I want for myself that don’t exist quite the way I want them. A colleague at work just builds whatever he thinks of now. I’m getting there.

The biggest current headache is cost. Claude Code API charges add up fast when you’re doing serious work, and last month I had enough overages that I’m now trialling whether running both Claude Code and ChatGPT’s Codex together is actually cheaper than paying for the next Claude tier up. Early signs are interesting.

And separately, with my new MacBook Air running 32 gigs of RAM, I’m finally in a position to run proper local models. I’ve started downloading and testing, and the early results suggest I might be able to replace some of what I’m using Lumo for with a local model that’s actually more private and possibly better. That’s an ongoing experiment.

It’s a lot. But honestly, talking to people now, whether friends, colleagues, or people in the industry, so many are either just scratching the surface or not looking at it at all. I was over a year late getting serious about this. I don’t think I’m late anymore.

Switching to Claude

I’ve been on this AI journey for a while now, and for most of it ChatGPT was my main tool. But in February 2026 that changed.

Someone whose opinion I trust recommended I give Claude a try after voicing my frustrations with ChatGPT. When I actually sat down to evaluate it I did something that in hindsight was pretty funny. I asked Claude directly why I should use Claude over ChatGPT.

It told me not to.

Based on what I told Claude I wanted, it said I’d probably get better results from ChatGPT. So naturally I didn’t trust that answer and kept pushing. As I interrogated it further it started explaining that it was slower and more thoughtful, and from its previous read of what I was looking for, it figured I wanted fast straight answers. And that’s when something clicked for me.

One of my biggest frustrations with ChatGPT was exactly that. I’d ask it something and it would just fire back an answer. Fast, confident, and often not what I actually asked for. Like if I asked for specific instructions on how to do something on an Apple product, it would give me generic steps that didn’t even exist in the actual interface. I’d have to stop it and say don’t give me fluff, give me the actual thing. Then it would have to go look it up and either admit it didn’t know or finally give me something useful.

What Claude was describing as a weakness, slower and more considered, was exactly what I wanted. So I signed up and started using both in parallel.

Early on I was genuinely impressed with what was coming out of Claude. I was using Sonnet, the middle tier model, and the difference in output quality was noticeable pretty quickly. The concern then was whether I’d end up paying for two services. I was already paying for Venice and Lumo on the privacy side and the last thing I wanted was more sprawl.

But it became clear fairly fast that Claude was where I wanted to be. Which meant I had to migrate everything I’d built in ChatGPT over the previous six months or so. Custom GPTs, saved prompts, all of it. I had to extract everything, make sure I had backups, build a little text based database of all my prompts, and systematically move it all across.

I got it done within a month and managed to avoid paying for both services at the same time for more than one month. Then I downgraded ChatGPT to the free tier and haven’t looked back.

From a reliability standpoint Claude is better. Not perfect, and everything I said in the last post about not trusting it still applies. But it’s a meaningful improvement. And honestly, switching to it unlocked a whole new level of what I started doing with AI. Which is what the next post is about.