I’ve been writing a lot about AI and tech projects lately, which makes sense since that’s the stuff that ends up on this blog. It isn’t all that’s going on in my life, just to be clear. But my AI setup has quietly evolved in August and September in a way that’s letting me undo a bunch of stuff I only built because of the cloud AI’s limitations, so here we go again.
First, the accounts. I’ve been using Claude a lot more than any other AI system lately, but I’m still mixed between Claude and ChatGPT for coding work. Instead of paying for Claude Max or the equivalent top tier ChatGPT plan, which run about five times the price of the regular subscription, I pay for two mid tier plans instead, the Claude Pro and the ChatGPT Plus. Partly that’s so when I run out of tokens on one, I can switch to the other. But that’s a small reason. The bigger ones are that if one gives me a bad answer, I want to try the other, and sometimes I want a second opinion and will ask both the same question. I also don’t think I’d actually use five times the usage, so paying for the bigger plan on either one would just mean I’m not getting my money’s worth. There are times I max out both in the same stretch, so maybe I am doubling up after all. Who knows.
Interesting side note, I’ve been leaning on Codex more for coding lately, with a bit of chat here and there. I like their interactive audio, though I don’t use it as much as I probably hold onto the idea of using it. I’m building sites and things with Codex now, not because I think it’s better, I started because a friend recommended it after I hit a specific wall with Claude. I still use Claude for coding too, but I keep them separate on purpose. Coding work tends to run a project’s token budget down fast, and I don’t want that eating into the day to day chatting I do in Claude. The coding side is pretty interchangeable between the two since everything gets saved locally to wherever I’m working anyway.
Now, the actual problem I’ve been solving. With ChatGPT, and then Claude once I moved to it, the challenge was always context. Take my car tracking prompts as an example. It’s one of many, holiday planning is another, so is tracking the general inventory of stuff I own, but let’s stick with the car since we’re actually replacing it with another used one right now. I’d feed it a lot of detail about the car, our usage, our spending, all of that. Then every new chat, I wanted it to already know the context, how to respond to me for that narrow kind of conversation. So I had some generic prompts, plus a very specific auto inventory prompt, and I’d load all of that into a fresh chat every time.
Then there’s the data itself. Registration, MOT dates, how much we paid for the car, fuel spend over the last couple of months. All stuff AI is genuinely good at trending and drawing insight from, and useful for research too. But I needed to save it somewhere. My old process was to have the prompt itself describe how to save the data, which in most cases meant getting the AI to structure everything into a JSON file I could download and keep a version of.
The problem is I don’t want to keep an indefinite chat going, especially with Claude, though ChatGPT has some of the same issue. As a chat gets long, the AI starts forgetting the earlier stuff and compacts it, and it even warns you this is happening. I wanted everything solid enough that if I deleted that chat and started fresh, the new one would already have everything the old one had.
So the prompts were only half the system. The other half was the JSON, or a CSV for a pure inventory file, sitting there holding the actual data. I built one of these little systems for the car, one for holiday planning, one for holiday budgeting, a stack of them, each with its own context switch. It worked, but it meant a real proliferation of chats. Start a chat, load the data, double check which version of the file I was working from, and when I was done for the day, have the AI spit out a fresh JSON with a version number in the filename and save it to disk. I ended up with thirty or forty versions of some of these files sitting around. Not done with the topic forever, just done with it for that session, so I’d save and move on, and next time load the latest one and keep going.
That whole dance existed because neither Claude nor ChatGPT could write to a file in its own project folder, only read from one. I could load something into a project, but I couldn’t have it write back out to that same spot. That was the actual limitation driving all of it.
Then, much more recently, within the last month or so, Claude’s Cowork got a lot easier to use and a lot more functional. It’s mid September as I’m writing this, and just yesterday I read that they’d simplified the interactions with it even further, which is great timing for me. With Cowork, I’ve gone back through each of my little systems and rewritten the prompts. Now I can just tell a new chat to look at a directory on my computer, read the markdown file with the instructions, read the JSON, and write straight back to that same JSON. No more versioning gymnastics on my end, because I don’t need to care about it anymore. Time Machine on my Mac is already snapshotting everything hourly and backing it up elsewhere, so the versioning is handled at the file system level, which is where it belonged all along.
I still keep these as separate projects in Claude, because I want specific context tied to specific folders on my computer. My car information lives under an auto folder inside a broader life inventory folder, my computers have their own folder, my domain names have theirs, each with its own markdown for how I want it handled. In the past I’d have to manually load the data file and the instructions file into Claude every single time I started up. Now the project just has a tiny instruction pointing to a markdown router, a file in the root directory that lists out all the different contexts I’ve got and where to find the detailed files for each one. It knows to go look in those folders, and inside something like auto, it’ll find an instructions markdown, the data file, and whatever else belongs there. I can start one omni chat for anything life inventory related, or a specific car chat, and either way it’s not my job to keep the local files in sync anymore, because that’s just handled.
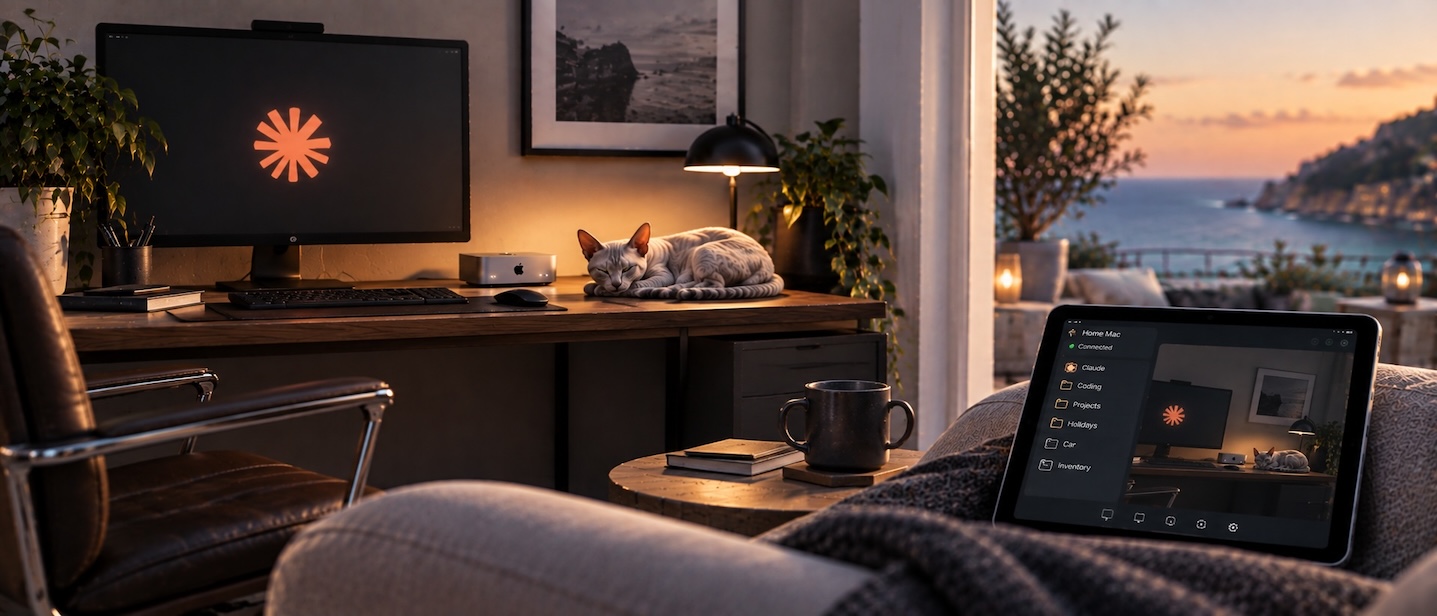
For a while I could already do a version of this on my own computer in a coding session, but not from the cloud, not from my phone on the couch, or my iPad while we’re figuring out where to go for dinner or nailing down holiday plans. Now with Cowork, I can start a session that runs as long as it needs to. I don’t care if it compacts and forgets things partway through, because all the data that matters is already saved to a file, and it’s got a remote session into my actual computer at home.
In another post I mentioned why I might end up getting a Mac Mini instead of relying on my MacBook Air, and this is exactly why. If I take the laptop with me, none of these sessions work, since there’s no computer at home to remote into. I’m fine with a dedicated home machine for this, because lately the only reason I’ve been taking a laptop anywhere has been to do AI stuff with it in the first place. It’s a bit circular. If I can run everything through a remote Cowork session back to a computer at home, I don’t need to bring a computer anywhere at all.
I’ve been going on holiday without a computer for a while now, aside from that one AI use case, to the point where I’ve packed the laptop a couple of times telling myself I might need it, and then never actually taken it out of the bag. My 11 inch iPad Pro has become my go to screen for everything, and this new Cowork setup makes that even more true than it already was.
So that’s where things have migrated to for now, and we’ll see how it keeps evolving. Ideally I’d love to get to a point where I don’t need a home computer in the loop at all and can just use remote storage instead. But I don’t use a mainstream service like Dropbox, OneDrive, or Google Drive, which is probably where that kind of direct read and write access would actually get supported first. Last I checked, Google at least would let you read from those places but not write back to them. When that changes, it’ll be worth revisiting, but for now I’m sticking with my own storage.
That’s the state of the AI setup as it stands. Check back in a couple of months to see how much of this I’ve already torn apart and rebuilt again.